


Databricks Data Engineering Training helps learners develop practical skills in building, managing, and optimizing data pipelines using the Databricks Lakehouse Platform. This Databricks Data Engineering Course covers Apache Spark, PySpark, Spark SQL, Delta Lake, data ingestion, and data transformation. Learn to process large datasets, develop ETL pipelines, implement batch and streaming workflows, and organize data using Bronze, Silver, and Gold layers. The course introduces lakehouse architecture, data quality, workflow orchestration, and performance optimization for modern data engineering environments. Databricks Online Training is suitable for aspiring data engineers, IT professionals, data analysts, and working professionals seeking to expand their technical skills. Learners also explore concepts relevant to the Databricks Certified Data Engineer Associate certification through practical exercises and projects. Build a foundation in Data Engineering with Databricks and understand how scalable data pipelines support analytics and business intelligence.
Databricks Data Engineering
Learn Databricks Data Engineering with Apache Spark, PySpark, Delta Lake, and data pipelines. This Databricks Training helps aspiring data engineers and working professionals develop practical data processing skills and prepare for Databricks certification.
Level
Advanced
Duration
8 Weeks
Placement Client


About Databricks Data Engineering
Training Plan

About trainer
Working professional who is carrying more than 10 years of industry experience.

Decks & Updated Content
Access to updated presentation decks shared during live training sessions.

e-Book
E-book provided by TechPratham. All rights reserved.

Assignments & MCQs
Module-wise assignments and MCQs provided for practice.

Video Recording
Daily Session would be recorded and shared to the candidate.

Projects
Live projects will be provided for hands-on practice.

Resume Building
Expert-guided resume building with industry-focused content support.

Interview Preparation
Comprehensive interview preparation with real-time scenario practice.
Databricks Data Engineering Course Curriculum
Data Engineering Courses
Additional Program Highlights
Comprehensive study materials and resources
Professional resume building session
Master your interview skills
Real-world project demonstrations
Upcoming Batches
Can't find a batch you were looking for?
Who Should Take Databricks Data Engineering Course?
IT Professionals
Non-IT Career Switchers
Fresh Graduates
Working Professionals
Ops/Administrators/HR
Developers
BA/QA Engineers
Cloud / Infra
IT Professionals
Non-IT Career Switchers
Fresh Graduates
Career Opportunities After Learning Databricks Data Engineering
Data Engineer
Databricks Data Engineer
Cloud Data Engineer
Junior Data Engineer
Big Data Engineer
ETL Developer
Data Pipeline Developer
Data Platform Engineer
Data Engineer
Databricks Data Engineer
Cloud Data Engineer
Key Projects
Databricks Data Engineering

Walmart – Retail Sales ETL
Scenario: Build a retail data pipeline for sales analytics in a simulated Walmart environment using Databricks.
Live Work:
- Ingest sales data using Auto Loader.
- Transform data using PySpark and Delta Lake.
- Create Bronze, Silver, and Gold tables.

Metro Bank – Banking Data Pipeline
Scenario: Develop a banking data pipeline for secure customer data processing and analytics using Databricks.
Live Work:
- Ingest customer records into Delta tables.
- Validate data using PySpark and Spark SQL.
- Apply access controls using Unity Catalog.

Deloitte – Customer Analytics ETL
Scenario: Develop a customer analytics pipeline for processing customer and transaction data in a simulated enterprise environment.
Live Work:
- Load customer data into Databricks.
- Transform datasets using PySpark and Delta Lake.
- Schedule and monitor jobs using Databricks Workflows.
Infosys – Supply Chain Data ETL
Scenario: Build a supply chain data pipeline for inventory and shipment analytics using Databricks.
Live Work:
- Ingest inventory data into Delta tables.
- Transform shipment data using PySpark.
- Schedule pipelines using Databricks Workflows.
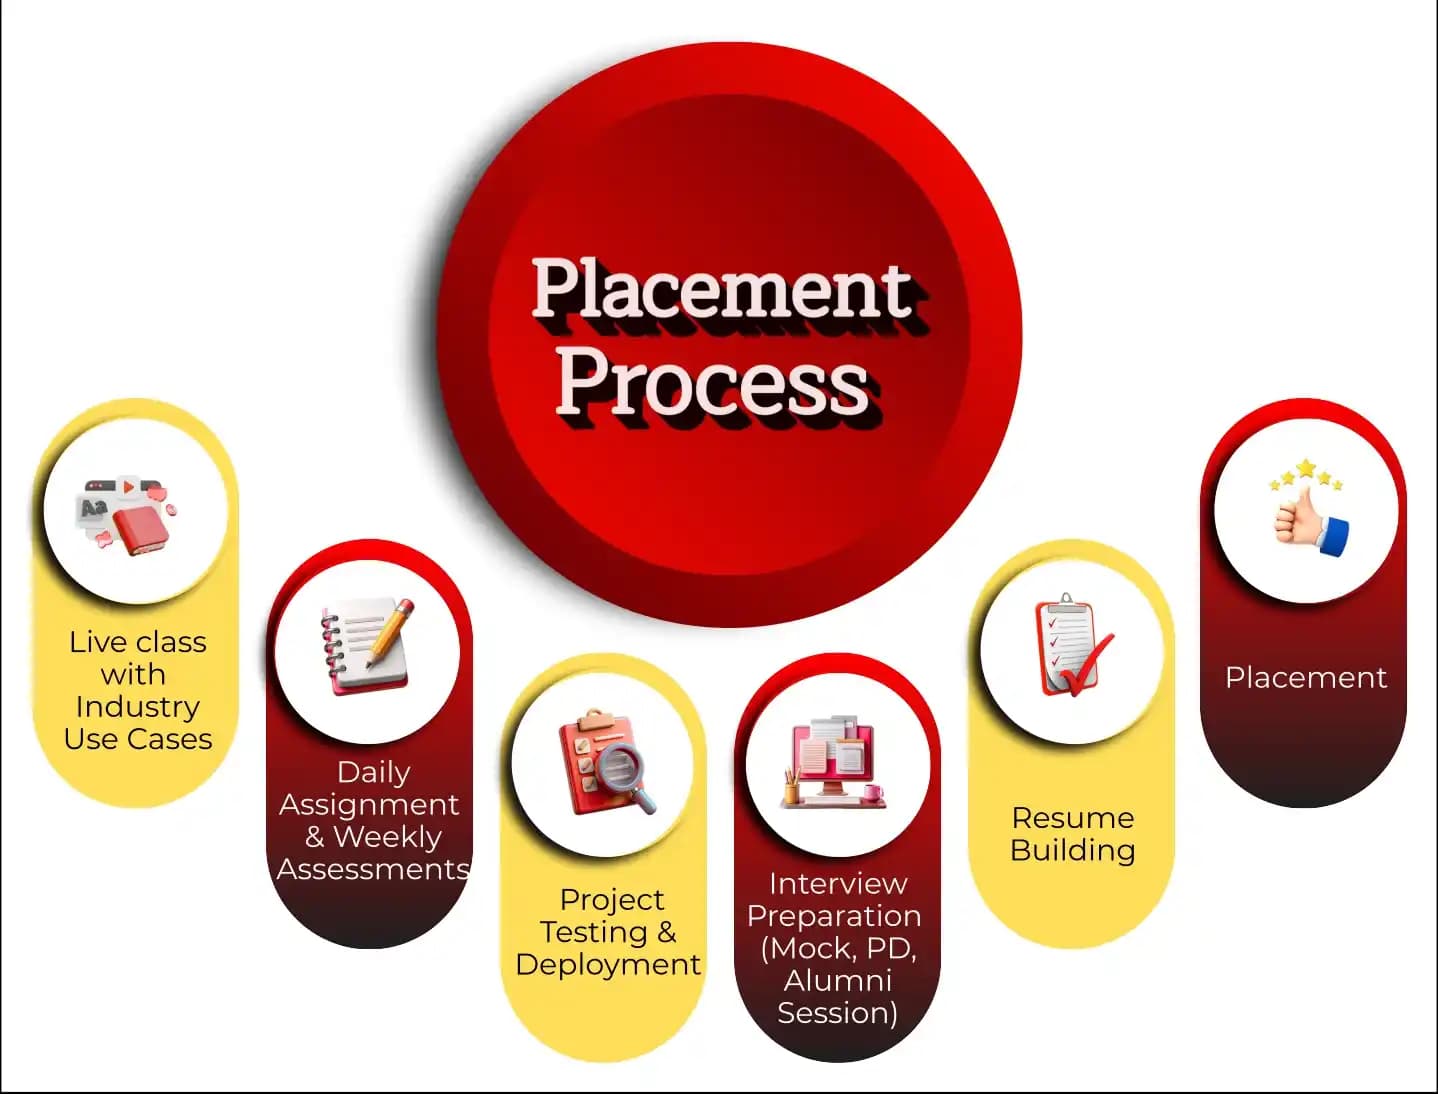
Placement Process

Live Class with Industry Use Cases
- Interactive learning
- Real-world examples
- Expert guidance
- Doubt resolution

Daily Assignment & Weekly Assessments
- Hands-on practice
- Concept reinforcement
- Weekly evaluation
- Timely feedback

Project Testing & Deployment
- Project development
- Testing practice
- Deployment exposure
- Portfolio creation

Interview Preparation (Mock, PD, Alumni Session)
- Mock interviews
- Personal development
- Alumni guidance
- Confidence building

Resume Building
- Resume crafting
- Industry-focused format
- Skills highlighting
- Professional presentation

Placement
- Job assistance
- Interview support
- Career guidance
- Opportunity access
Latest Hiring
Recently Placed Candidates
Latest Hiring
Our Success Mantra
 Commitment
- Ensuring quality training every day
 Fulfillment
- Meeting learning goals with confidence
 Accomplishment
- Students achieving industry-ready expertise
Our Learner Voice
Loading reviews...
Beyond Courses:
Additional Support We Provide
24/7 Support
LinkedIn Profile
Resume Writing
Alumni Sessions
Interview Preparation
Live Projects
What Makes TechPratham Training Different?
What is Databricks Data Engineering?
Who can enroll in the Databricks Data Engineering course?
Do I need programming experience to learn Databricks?
What technologies are covered in Databricks Data Engineering training?
Is Databricks Data Engineering suitable for working professionals?
What is the Databricks Lakehouse Platform?
What is Apache Spark, and why is it used in Databricks?
What is the difference between Spark transformations and actions?
What is the difference between a Spark DataFrame and an RDD?
What is Delta Lake, and how does it differ from a regular data lake?
What is the purpose of the Bronze, Silver, and Gold layers?
What is Auto Loader in Databricks?
Databricks Certified Data Engineer Associate
Industry-Recognized Certification
News Highlights
Featured In
About Us
TechPratham is an ISO 9001:2015 certified IT Training and Development, delivering industry-focused certification courses with expert guidance and placement support.
 +91-8882178896
 +1 (343) 477-0926